2,601 (edited by Santr 14-05-2026 15:37:39)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

AutumQueen92 wrote:

Anyone using 48fps or 72fps videos on a 120hz monitor? It seems to be smooth at times, and 120fps does not seem to have a big difference in comparison

If we're talking 24fps videos interpolated to 48 or 72, then yes, although mine is a 165Hz monitor. But x4 (96fps) is a noticeable step up from x3 (72fps) to my eye. More then that I can also notice but it's not as critical as getting to that x4.

One thing to note is that SVP is only half of the equation. The other half is to draw those frames in sync with your monitor, otherwise even 160fps will remain jittery.

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Santr wrote:
AutumQueen92 wrote:

Anyone using 48fps or 72fps videos on a 120hz monitor? It seems to be smooth at times, and 120fps does not seem to have a big difference in comparison

If we're talking 24fps videos interpolated to 48 or 72, then yes, although mine is a 165Hz monitor. But x4 (96fps) is a noticeable step up from x3 (72fps) to my eye. More then that I can also notice but it's not as critical as getting to that x4.

One thing to note is that SVP is only half of the equation. The other half is to draw those frames in sync with your monitor, otherwise even 160fps will remain jittery.

Try 120hz if you can.  It uses a little more GPU resources with SVP but it is divisible by 48 and the added smoothness is worth it.

2,603 (edited by GeoFly 18-05-2026 23:16:36)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

zxcvbnm821 wrote:
Chainik wrote:

> If the RIFE v2 models use fewer GPU resources and produce better visual quality than the v1 models

because they don't

Wait, what?! I always assumed v2 was strictly better than v1. Was I completely wrong?

The v2 models cause stutter for me. I get reduced GPU usage, however there is stutter in the playback without any dropped frames. When I switch back to the v1 models (e.g. 4.25_lite), the stutter goes away.

I've got a 4080 doing 4k from 23.976 fps to 48 Hz.

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Panning lags without v sync only g sync is there a way to make everything as smooth as it is with v sync but without v sync with only g sync ?

2,605 (edited by Drakko01 22-07-2026 18:16:45)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

I am having an issue trying to use the new VapourSynth R78 candidate release with SVP.Previously, when testing versions (like up to R77), I would simply replace the vapoursynth.dll file as usual, and everything worked perfectly. However, after doing the exact same thing with the new R78 DLL, my video player just  closes instantly whenever I try to open a video.If I revert back to the R77 DLL, the player works normal again.(any player)

I know that R78 introduced a breaking change or an API update that causes SVP or the player script to crash.
Does anyone know a way to make R78 work with SVP manually, and what exactly do I need to change? Is there another file or configuration I need to modify.

Thanks in advance for any help!

2,606

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

I have been using this setting to play all of my anime these days, its been great for me, but can it get any better?
Should I change my AI model to 4.26 Heavy?
Any suggestion?

Post's attachments

SVP.png, 59.24 kb, 550 x 603
SVP.png 59.24 kb, 86 downloads since 2026-07-31 

2,607

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

hvs wrote:

Should I change my AI model to 4.26 Heavy?

I'd suggest trying 4.22 Lite and 4.25 Heavy. Both are good quality-wise but while 4.25 Heavy is slightly better, it comes at a very high performance cost. 4.22 Lite has become my default.
With 4.26 models, I've experienced some pretty bad artifacts, so would not recommend. YMMV.

2,608 (edited by flowreen91 06-08-2026 06:19:40)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Can anyone check performance for latest TensorRT RTX?
They just fixed a crash that was happening at weird video sizes:
https://gyazo.com/bc40853110360394cd72264eea910699
+ it still has the benefit of building the rife engine faster than current TensorRT non-RTX so we should switch if looks like improvement...

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Nevermind, asked Fable and it did some tests:

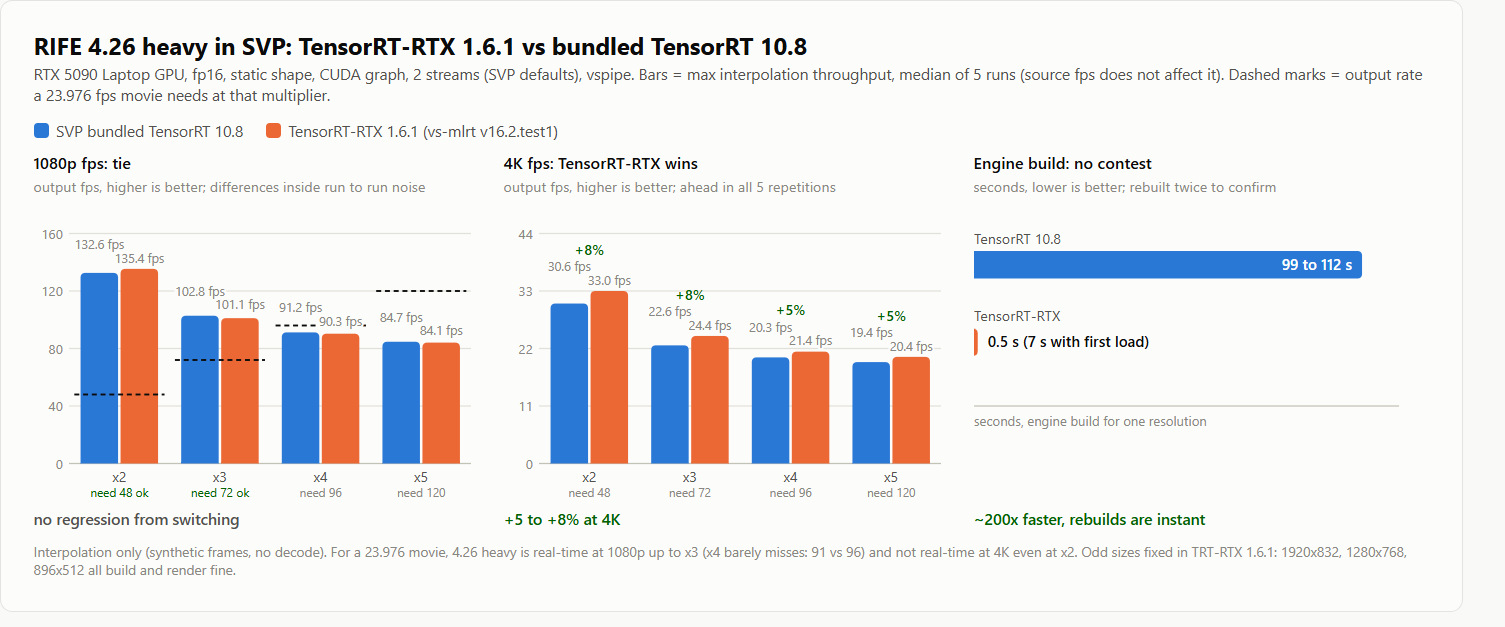
The setup: RTX 5090 Laptop GPU, SVP's bundled stack (TensorRT 10.8, vstrt.dll) vs TensorRT-RTX 1.6.1 (vs-mlrt v16.2.test1 vstrt_rtx.dll), RIFE 4.26 Heavy, fp16 + static shape + CUDA graph + 2 streams (SVP defaults), synthetic source through vspipe, so the numbers are max interpolation throughput and source fps does not change them. Numbers below are TensorRT vs TensorRT-RTX, median of 5 runs per config; the dashed marks in the chart show what a 23.976 movie needs at each multiplier:

https://i.gyazo.com/5ba59183e64e59e029c4a87da7c25899.png

1080p (1920x1088): x2 132.6 vs 135.4, x3 102.8 vs 101.1, x4 91.2 vs 90.3, x5 84.7 vs 84.1. Identical within run to run noise.
4K (3840x2176): x2 30.6 vs 33.0, x3 22.6 vs 24.4, x4 20.3 vs 21.4, x5 19.4 vs 20.4. TensorRT-RTX is 5-8% faster and won every single repetition.
For a 23.976 movie that means 4.26 Heavy is real-time at 1080p up to x3 (x4 barely misses, 91 vs 96 needed) and not real-time at 4K even at x2.

Engine build for 4.26 Heavy: 99 to 112 seconds on TensorRT 10.8 vs 0.5 seconds on TensorRT-RTX (about 7 seconds total setup including first engine load). Rebuilt engines from scratch twice per backend to confirm, it holds.

Also confirmed the weird-size crash is really fixed in 1.6.1: 1920x832, 1280x768 and 896x512 all build and render fine.

So: same speed at 1080p, faster at 4K, and the 100 second engine build basically disappears. Looks like a clear win. SVP's script generator already has the rife_rtx hook that loads vstrt_rtx.dll, it just needs the updated rife package (vstrt_rtx.dll + tensorrt_rtx DLLs + newer vsmlrt.py).

2,610

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Drakko01 wrote:

I am having an issue trying to use the new VapourSynth R78 candidate release with SVP.Previously, when testing versions (like up to R77), I would simply replace the vapoursynth.dll file as usual, and everything worked perfectly. However, after doing the exact same thing with the new R78 DLL, my video player just  closes instantly whenever I try to open a video.If I revert back to the R77 DLL, the player works normal again.(any player)

I know that R78 introduced a breaking change or an API update that causes SVP or the player script to crash.
Does anyone know a way to make R78 work with SVP manually, and what exactly do I need to change? Is there another file or configuration I need to modify.

Thanks in advance for any help!

I previously submitted this , but it has been completely ignored.It seems like nobody cares about this or sees any value in it.

2,611

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

flowreen91 wrote:

SVP's script generator already has the rife_rtx hook that loads vstrt_rtx.dll, it just needs the updated rife package (vstrt_rtx.dll + tensorrt_rtx DLLs + newer vsmlrt.py).

How can I properly use rife_rtx?
Here is what I have done so far:
Placed tensorrt_onnxparser_rtx_1_6.dll, tensorrt_rtx_1_6.dll, and tensorrt_rtx.exe into SVP 4\rife\vsmlrt-cuda.
Placed vstrt_rtx.dll and the updated vsmlrt.py into SVP 4\rife.
However, it doesn't seem to work: SVP still uses the regular TensorRT backend (resulting in slow engine compilation) instead of TensorRT-RTX.
Could someone explain how to correctly trigger or activate rife_rtx in SVP 4? Thanks!

2,612

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

for me _rtx is significantly slower (on the 4070), last time I tried was ~half an year ago
plus, it doesn't need "slow engine compilation", yes, BUT it's much slower at initialization. TRT runs instantly after the initial engine compilation, TRT_RTX needs some time at every run and every seek.

2,613 (edited by flowreen91 Today 11:20:10)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

If you want to apply TensorRT-RTX, do this:

https://drive.google.com/drive/folders/ … XX-S2JMOXD

1. Close SVP.
2. Make a backup of your "SVP 4" folder.
3. Copy the "SVP 4" folder from the archive on top of yours, overwrite all.
4. Start SVP and use RIFE as usual.

Nothing else to configure. The first time a model or a resolution is used
it prepares the engine by itself, after that it is cached.

Numbers here, RTX 5090 Laptop, model 4.6, x2, 5 runs each:

                      TensorRT      TensorRT-RTX
1080p                261.8 fps       267.4 fps
4K                    60.0 fps        62.8 fps
engine build 1080p       103 s            12 s
engine build 4K          122 s            14 s
seek in mpv              0.9 s          0.45 s
runtime files          2565 MB          222 MB

The last row is what the two backends need on disk to build and run engines.
The archive does not remove anything from your install, it adds the RTX
runtime next to what you already have, but it shows what SVP could ship
instead of the old TensorRT 10 builder libraries.

2,614

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Chainik wrote:

for me _rtx is significantly slower (on the 4070), last time I tried was ~half an year ago
plus, it doesn't need "slow engine compilation", yes, BUT it's much slower at initialization. TRT runs instantly after the initial engine compilation, TRT_RTX needs some time at every run and every seek.

You are right, and I measured exactly that: 7.7 seconds per seek against 0.9 s
on the current backend. Then I looked at where the time goes, and it turned out
to be fixable.

TensorRT-RTX compiles its kernels when an execution context is created, not
when the engine is loaded. Loading the engine is 0.04 s. Creating the contexts
is 3 s for one stream, 4 s for two. A player throws away its whole VapourSynth
graph on every seek, so that cost was paid again on every jump.

Two changes in the vs-mlrt plugin:

1. Keep the compiled kernels. TensorRT-RTX has IRuntimeCache for this, vs-mlrt
   master does not use it yet. The plugin now stores it next to the engine,
   about 3 MB.
   Seek goes from 7.7 s to 3.1 s.

2. Stop rebuilding. The loaded engine and its contexts now go into a small pool
   when the filter is destroyed and come back when it is created again, so a
   seek reuses them instead of building them. Seek goes to 0.45 s.

                  TensorRT      TensorRT-RTX
seek in mpv          0.9 s          0.45 s
runtime files      2565 MB          222 MB

So the initialization cost you remember is gone on my side, and the 100 second
engine build stays gone. Opening a file still costs about 2 s more than TRT,
only seeks are solved.

About it being slower: that was half a year ago. With 1.6.1 the odd-size crash
is fixed and the speed is 261.8 vs 267.4 fps at 1080p and 60.0 vs 62.8 at 4K
(model 4.6, x2). A 4070 may land differently, the archive in my previous post
is ready to copy over an install if you want to retest.

Source attached: the diff against vs-mlrt master, both patched files, the build
command, and a README with the API calls, the two environment switches to turn
the changes off, and the cost of the pool (it holds the engine, 464 MiB here,
until the entry is evicted or the player closes).

The pool is Windows only as written, it pins the plugin DLL in the process, a
Linux equivalent probably exists but I have not looked.

Post's attachments

vstrt-rtx-fast-seek-source.zip 20.4 kb, 2 downloads since 2026-09-20 

2,615 (edited by pituz Today 16:03:12)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

flowreen91 wrote:

If you want to apply TensorRT-RTX, do this:
1. Close SVP.
2. Make a backup of your "SVP 4" folder.
3. Copy the "SVP 4" folder from the archive on top of yours, overwrite all.
4. Start SVP and use RIFE as usual.

Thanks for response! But I've got error after replacing files.
https://i.ibb.co/Jj2KgBRM/1.png

2,616

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

flowreen91

> About it being slower: that was half a year ago.

dunno. just tried on a laptop with 2060:
TRT: 33.7 fps
TRT-RTX 1.4: 23.9 fps
TRT-RTX 1.6: 21.6 fps

----------
btw, instead of "fixing" generate.js, just add a "rife_rtx" profile option via "user defined options" wink

2,617

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

> With 1.6.1 the odd-size crash is fixed and the speed is 261.8 vs 267.4 fps at 1080p and 60.0 vs 62.8 at 4K (model 4.6, x2).

is it possible that 5090 is not a bottleneck in your case?
what is the GPU load?

2,618 (edited by flowreen91 Today 22:40:51)

Re: New RIFE filter - 3x faster AI interpolation possible in SVP!!!

Chainik wrote:

is it possible that 5090 is not a bottleneck in your case?
what is the GPU load?

GPU load is 98%. I attached the benchmark I use (svp-rife-bench.zip), so you can
run the same test. It only needs an SVP 4 install: it uses SVP's own VSPipe and
a synthetic clip, so no video file, decoder or display is involved. The GPU is
the only thing working, and numbers are comparable between machines. Unpack, run
run_svp_rife_bench.cmd, details are in the README.

My numbers from that test (5090)

max output fps at x2, 2 GPU threads, best of 3 runs (a 24 fps video at x2 only
needs 48):

resolution  model     TensorRT   TensorRT-RTX   RTX vs TRT
1080p       4.6         312.8       312.5         same
1080p       4.6 v2      330.7       349.1         +5.6%
4K          4.6          71.9        74.8         +4.0%
4K          4.6 v2       77.6        83.6         +7.7%

v2 is also faster than v1: 6 to 8% on TensorRT, about 12% on TensorRT-RTX.

Archive updated: v2 models now work
https://drive.google.com/drive/folders/ … XX-S2JMOXD

The archive is updated to support the v2 models. That fixes the crash pituz hit.
Please re-download before testing. The v2 models are the "(v2)" entries in the
"AI model" list, for example "4.6 (v2)", and they show up there once their files
are in rife\models\rife_v2.

I also did what you suggested: generate.js is no longer patched. TensorRT-RTX is
now switched on with a "rife_rtx" user defined option. How to enable it:

1. Close SVP and any player, back up the SVP 4 folder.
2. Copy the "SVP 4" folder from the archive over "C:\Program Files (x86)\SVP 4"
(needs admin rights once).
3. Start SVP, then main menu -> Application settings -> "User defined options"
tab, fill in the fields below and press "Add option".

Title:          TensorRT-RTX   (any text, it is just the label)
Script name:    rife_rtx       (this exact name matters)
Option scope:   FRC profile
Allowed values: ON or OFF

4. Open your RIFE profile. At the bottom there is now a "User defined options"
section with a "TensorRT-RTX" row: set it to On. "Neural network engine" must
still be "NVIDIA TensorRT".
5. Play a video.

The second attachment is a screenshot of both places: the option being added on
the right, and the "TensorRT-RTX" row set to On in the profile on the left.

Off is the default and gives exactly stock SVP behaviour, so the option is safe
to leave in place.

What I bumped into: v2 models gave corrupted frames on TensorRT-RTX

Every interpolated frame had a checkerboard of blown pixels over the whole
picture. A speed test cannot show this, I only saw it when I compared the output
frames. I should have checked sooner.

What breaks:

* v2 model + TensorRT-RTX 1.6.1: corrupted
* v2 model + plain TensorRT: fine
* v1 model + either backend: fine

Why: the v2 models compute their warp grid from the tensor shape at runtime
(ops: Shape, Gather, Range, Expand, Where, Equal, ConstantOfShape). TensorRT-RTX
1.6.1 miscompiles that part of the graph. The v1 models do not have those ops.
It is not a precision problem: a pure fp32 engine shows the same corruption, and
the same fp16 graph is correct on plain TensorRT.

Fix (in the updated archive): constant-fold that part of the graph for the
padded resolution before building the engine. After that, TensorRT-RTX and
TensorRT output is bit identical. Folding takes 0.3 s, once per model and
resolution. The engine is already cached per resolution, so the folded model
sits next to it.
Post's attachments

rife_rtx-user-defined-option.png 147.83 kb, file has never been downloaded. 

svp-rife-bench.zip 4.98 kb, file has never been downloaded.